> For the complete documentation index, see [llms.txt](https://docs.borndigital.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.borndigital.ai/digital-agent/conversation-flow/setting-tab.md).
# Setting tab
Project settings in File › Settings: intent recognition thresholds, text pre-processing, chat delays, vocabulary and stop words.
The project settings are in the flow editor under **File** › **Settings**:
* **Configuration** – language, intent recognition and text pre-processing,
* **Vocabulary** – words to replace in the customer's message,
* **Stopwords** – filler words removed from the customer's message.
Most settings affect only **Training set** intents, which use a trained language model. Chat buttons, Keywords, Condition and AI intents are not affected by the thresholds. After changing the pre-processing or training settings, **train the version again**.
## Configuration
### General
| Setting | Meaning | Default |
| ---------------- | ---------------------------------------------------------- | ------- |
| **Project name** | The name of the project (read-only here). | – |
| **Description** | A short summary of the project for your team. | empty |
| **Language** | The language of the project – see [Languages](#languages). | – |
| **Start node** | The node every conversation starts in. | START |
### Intent recognition (Training set intents)
| Setting | Meaning | Values | Default |
| ----------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------- | -------------- | -------- |
| **Intent threshold** | The minimum score the best intent must exceed to be selected. | 0.05–0.95 | 0.6 |
| **Intent relative threshold** | If the best intent does not pass the intent threshold, it is still selected when its score is more than this many times the second-best one. | 1.5–30 | 10 |
| **Original intent threshold** | The minimum raw confidence of the model. Below it, no intent is selected. | 0.000001–0.005 | 0.000001 |
| **Epoch** | How many times the model goes through the training set during training. Recommended 3–15. | 1–100 | 3 |
| **Learning rate** | How fast the model learns during training. | 0.05–0.95 | 0.1 |
Thresholds and other settings in File › Settings › Configuration
When no intent passes, the Answer node's **Fallback** is used. When only one intent can be reached from the node, it is selected without these checks.
#### Example
The customer writes *"I want to see my bill"*. The model gives these raw scores: **invoice** 0.0030, **payment** 0.0006, **cancel** 0.0004. Divided by their sum, the scores are 0.75, 0.15 and 0.10.
1. **Original intent threshold** (0.000001): 0.0030 is higher – continue.
2. **Intent threshold** (0.6): 0.75 is higher – **invoice** is selected.
With the **Intent threshold** at 0.8, step 2 fails and the relative test decides: 0.15 × 10 = 1.5 is more than 0.75, so the model is not sure enough and the **Fallback** is used. With the **Intent relative threshold** at 4, the result is 0.15 × 4 = 0.6, which is less than 0.75 – **invoice** is selected.
Raise the thresholds when the agent picks wrong intents; lower them when it falls back too often although the intent was right. Improving the training set usually helps more than changing the thresholds – see [Best practices for writing training set](/digital-agent/conversation-flow/training-set/best-practices-for-writing-training-set.md).
### Pre-processing of the customer's message
Before a Training set intent is recognised, the message is normalised: vocabulary replacements, number and e-mail detection, tokenization, spelling correction and stop-word removal. Keywords with **Use pre-processed utterance** and the variable `preprocessed_utterance` use the same normalised text.
| Setting | Meaning | Default |
| -------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------- |
| **Aspell** | Spelling correction: **replace** keeps only the corrected word, **duplicate** keeps the original and the corrected word, **whitelist** applies only Born Digital's list of corrections, empty turns it off. Not available for Korean. | replace |
| **Stopwords** | Removes stop words – see [Stopwords](#stopwords). | on |
| **Tokenizer** | How the message is split into words: `nist`, `split`, `cleversplit` or `notokenization`. | nist |
| **Disable utterance processors** | Turns all pre-processing off. **Studio sets it automatically** when you train: on when the flow has no Training set intents, off when it has some. | automatic |
{% hint style="info" %}
**Lemmatizer**, **Allow jumping** and **Nodes allowed to jump to** are no longer used – leave them empty. **Disabled utterance transformers** currently has no effect.
{% endhint %}
### Chat timing
| Setting | Meaning | Default |
| -------------------------- | ------------------------------------------------------------------------------------------- | ------- |
| **Speed coefficient** | How long the agent waits between two messages, based on their length. Smaller means faster. | 0.3 |
| **Max delay milliseconds** | The longest pause between two messages. | 2500 |
### Editor
**Zoom threshold** decides from which zoom level the flow editor shows the full content of the nodes. It does not affect the conversation.
## Vocabulary
The vocabulary replaces words or phrases in the customer's message before the intent is recognised – typically to fix words the speech recognition often gets wrong, or to unify synonyms.
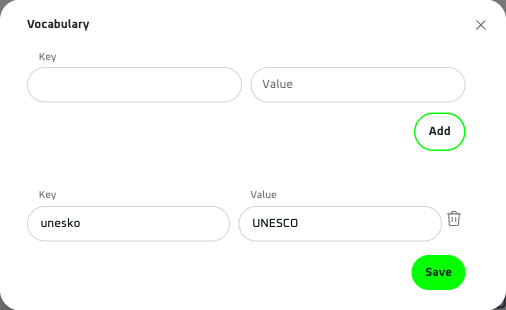
1. Open **File** › **Settings** › **Vocabulary**.
2. Enter the **Key** – the text to find – and the **Value** to replace it with, then click **Add**.
3. Click **Save** and train the version again.
A vocabulary entry before saving
* Keys are matched as **whole words**, regardless of upper and lower case. A key can be a regular expression.
* Each place in the message is replaced once; when keys overlap, the first one in the list wins.
* Replaced words are protected from the spelling correction.
* The vocabulary affects only the pre-processed message. It has no effect when the flow has no Training set intents, and it does not change speech recognition itself.
## Stopwords
Stop words are frequent filler words – for example *the*, *a*, *please* – that carry no meaning for intent recognition. They are removed from the pre-processed message as the last step. They do not stop or change the conversation.
* Each project language has a default list of stop words.
* Open **File** › **Settings** › **Stopwords** to make your own list. **Your list replaces the default list** – it is not added to it.
* Enter single words in lower case; phrases are not matched.
* Turn stop-word removal off with **Stopwords** in **Configuration**.
## Languages
**Language** in **Configuration** offers the languages supported by the trained intent recognition (Training set intents) and the text pre-processing: Arabic (`ar`), Czech (`cs`), Dutch (`nl`), English (`en`), French (`fr`), German (`de`), Hungarian (`hu`), Korean (`ko`), Polish (`pl`), Romanian (`ro`), Russian (`ru`), Slovak (`sk`), Spanish (`es`) and Mexican Spanish (`es-MX`).
The **Create project** dialog offers a longer list of languages. The project language also selects the language of speech recognition and speech synthesis in calls.